How to Build RAG Applications Using the MERN Stack and Next.js
On this page
- What RAG does and where the MERN stack fits
- What you need before you start
- How to build RAG applications using the MERN stack and Next.js
- Create the Next.js project and install the packages
- Connect to MongoDB with a cached connection
- Define the chunk model and the vector index
- Embed the chunks and save them in an ingestion route
- Retrieve the closest chunks with a vector search
- Generate and stream the answer in a chat route
- Build the chat page
- How to check that the whole system works
- Where to improve next
- Common questions
- Do I still need Express?
- Why store vectors in MongoDB instead of a separate vector database?
- Do I need LangChain?
- Next steps
How to Build RAG Applications Using the MERN Stack and Next.js
Ask a general chatbot about your company's refund policy and it will happily invent one. Retrieval-augmented generation (RAG) fixes that by fetching the right passages from your own data and handing them to the model along with the question. This guide shows how to build RAG applications using the MERN stack and Next.js, with MongoDB Atlas holding the vectors. You will finish with a working chat app that answers from your documents.
What RAG does and where the MERN stack fits#
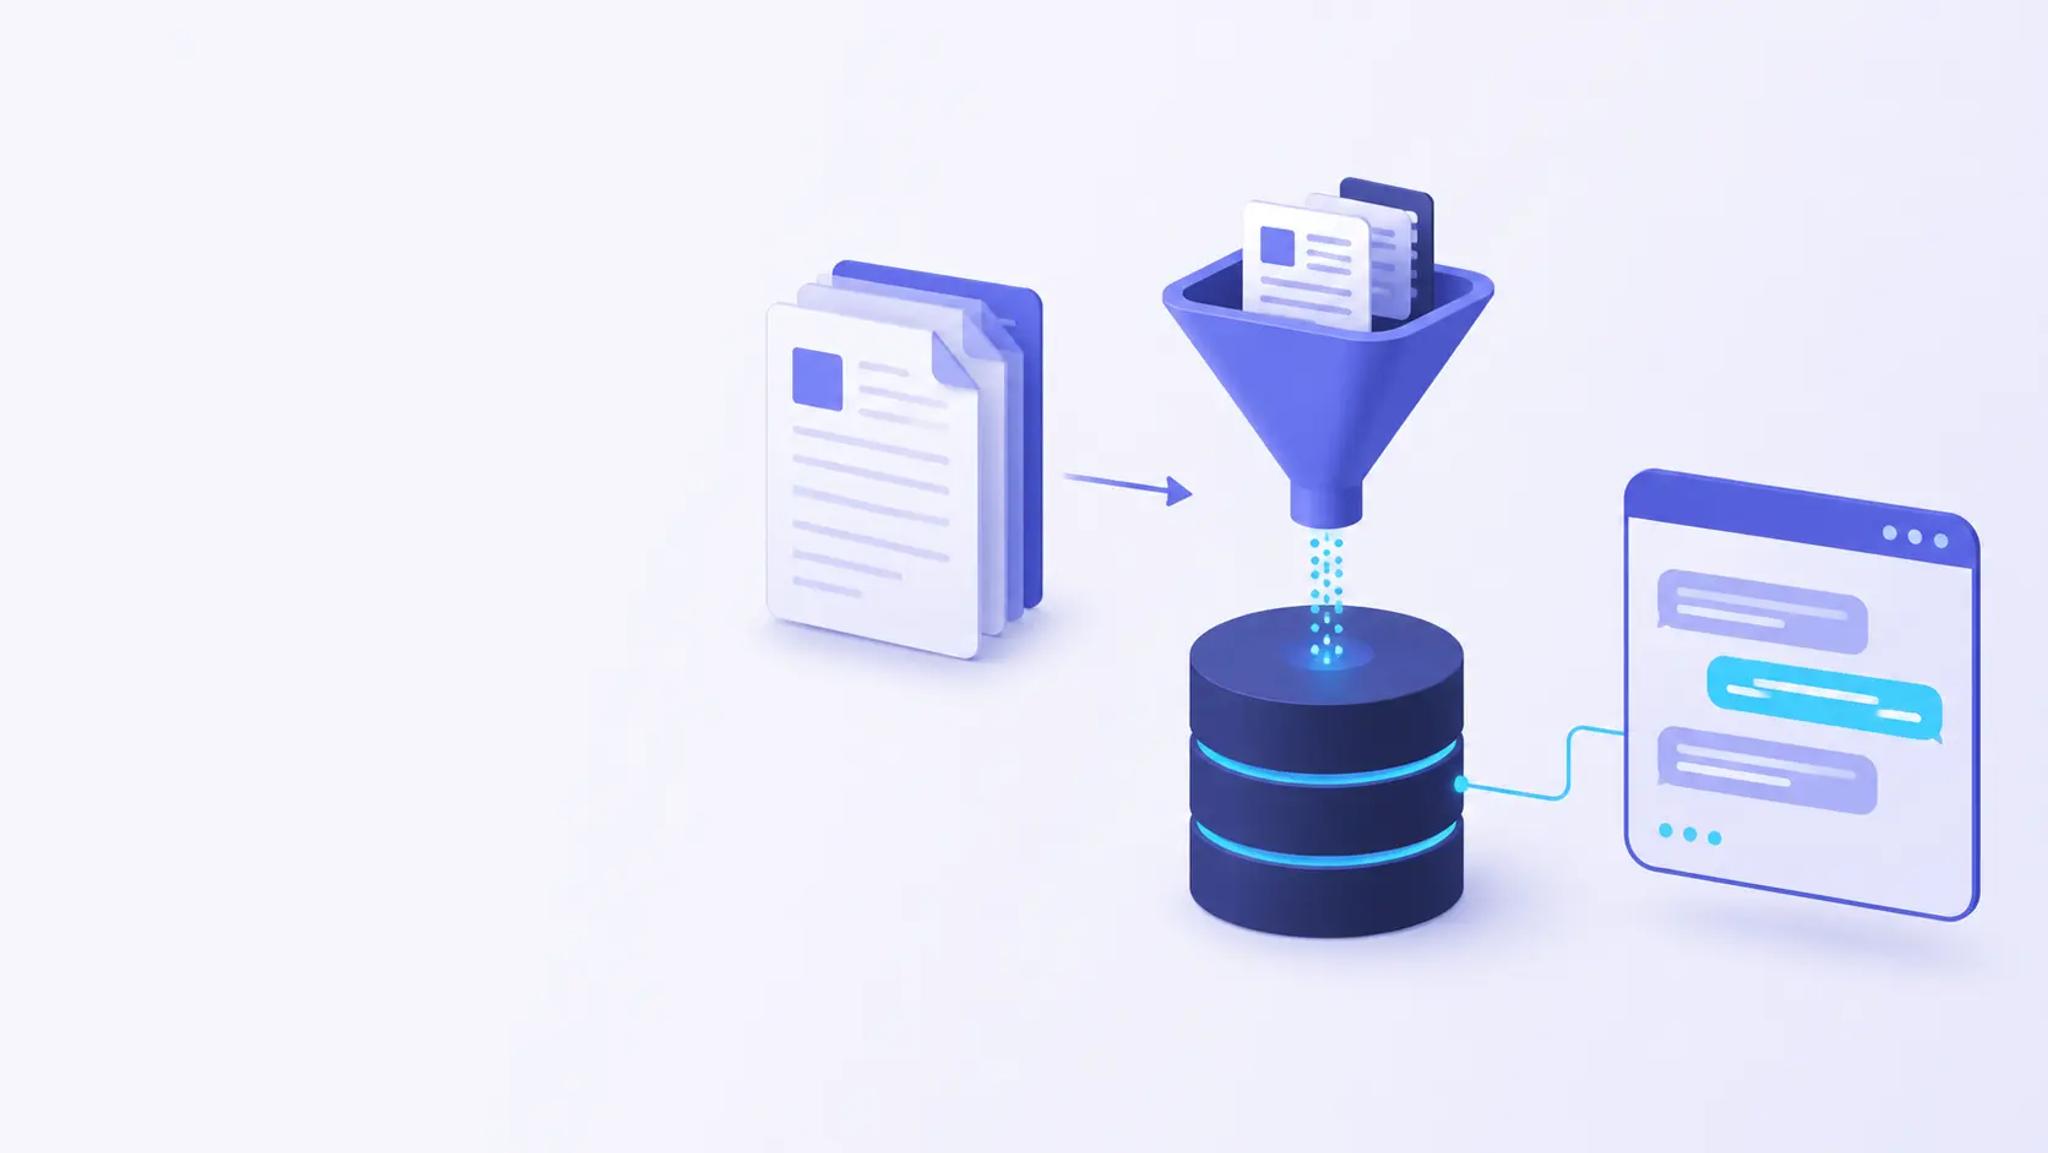
A RAG system has two flows. The first prepares your data, and the second answers questions with it. MongoDB's RAG tutorial describes the same sequence. Split data into chunks and convert them to vectors with an embedding model. Store the vectors, retrieve the closest matches, then pass the question and matches to a language model. You can read the MongoDB RAG tutorial for its full version.
MERN stands for MongoDB, Express, React and Node.js. Next.js takes over the React front end, and its Route Handlers can replace most Express routes. MongoDB and Node.js stay exactly where they were. If you already run a separate Express API, keep it for ingestion and let Next.js call it. The full stack developer roadmap shows where this stack sits in a wider learning path.
Here is the shape of what you will build:
- Ingestion: text goes in, gets split into chunks, turned into embeddings and saved in MongoDB.
- Question answering: a question is embedded, the closest chunks are found, and the model answers from them while the reply streams to the browser.
What you need before you start#
- A recent Node.js LTS release and basic TypeScript
- A MongoDB Atlas cluster and its connection string
- An API key for Vercel AI Gateway, which serves both embeddings and chat models
- A few text documents to test with, such as a policy page or a course syllabus
- Some React knowledge, which our React JS training in Kochi can build if you need it
The code below was written for the App Router and the AI SDK as documented in November 2026. The AI SDK has changed its function names between major versions, so compare each import with the docs for the version you install.
How to build RAG applications using the MERN stack and Next.js#
Create the Next.js project and install the packages
Run npx create-next-app@latest rag-app and accept the TypeScript and App Router options. Then install the libraries with this command:npm install mongoose ai @ai-sdk/react @ai-sdk/gatewayCreate a .env.local file with two values: MONGODB_URI for your Atlas connection string and AI_GATEWAY_API_KEY for the gateway. Vercel's embeddings guide expects that exact variable name.
You should now be able to run npm run dev and open the starter page on localhost. The most common mistake here is committing the .env.local file, so keep it out of git.
Connect to MongoDB with a cached connection
Next.js reloads modules whenever you save a file in development. Without a cache, each reload opens a fresh database connection. Store the connection promise on globalThis so it is reused.// lib/mongodb.tsMongoose needs the Node.js runtime, so every route that uses it should export
import mongoose from 'mongoose';
const globalForMongoose = globalThis as unknown as {
mongooseConn?: Promise<typeof mongoose>;
};
export function connectDB() {
if (!globalForMongoose.mongooseConn) {
globalForMongoose.mongooseConn = mongoose.connect(process.env.MONGODB_URI as string);
}
return globalForMongoose.mongooseConn;
}runtime = 'nodejs'. The Next.js Route Handlers reference lists that segment option.
Define the chunk model and the vector index
Each stored chunk keeps its text, its source and its embedding. The vector index tells Atlas which field holds the embeddings, how long each vector is and how to measure similarity. The Mongoose guide to Atlas Vector Search uses this index shape with schema.searchIndex().// models/Chunk.tsBuild the index once by calling
import { Schema, models, model } from 'mongoose';
const chunkSchema = new Schema({
text: { type: String, required: true },
source: { type: String, required: true },
embedding: { type: [Number], required: true },
});
chunkSchema.searchIndex({
name: 'vector_index',
type: 'vectorSearch',
definition: {
fields: [
{ type: 'vector', path: 'embedding', numDimensions: 1536, similarity: 'cosine' },
],
},
});
export const Chunk = models.Chunk || model('Chunk', chunkSchema);await Chunk.createSearchIndexes() from a throwaway script or a temporary route, then delete that code. The value numDimensions must match your embedding model's output length. For text-embedding-3-small that is 1536 [NEEDS SOURCE].
Atlas builds the index in the background, so wait until it shows as ready in the Atlas interface. A wrong numDimensions value is the usual reason searches return nothing.
Split your documents into chunks
Models read limited text, and a search that returns a whole manual is useless. MongoDB's tutorial lists several chunking strategies, including fixed size, fixed size with overlap, recursive and semantic splitting. Start with the simplest, fixed size with overlap, so a sentence cut at one boundary still appears whole in the next chunk.// lib/chunk.tsThe numbers 1000 and 150 are starting points to tune, not rules. Chunks that are too large blur the match, and chunks that are too small lose the context around a fact.
export function splitText(text: string, size = 1000, overlap = 150): string[] {
const chunks: string[] = [];
for (let start = 0; start < text.length; start += size - overlap) {
const piece = text.slice(start, start + size).trim();
if (piece) chunks.push(piece);
}
return chunks;
}
Embed the chunks and save them in an ingestion route
An embedding is a list of numbers that places a piece of text on a map of meaning, so similar passages land close together. The AI SDK's embedMany function creates them in one call. Vercel's AI Gateway embeddings guide shows the same call with the openai/text-embedding-3-small model.// app/api/ingest/route.tsPost a document with a tool such as curl and you should get back a count of stored chunks. Check the collection in Atlas to confirm each document holds an array of numbers. Leaving this route unprotected is the mistake to avoid, because anyone who finds it can fill your database and spend your API credit.
import { embedMany } from 'ai';
import { connectDB } from '@/lib/mongodb';
import { Chunk } from '@/models/Chunk';
import { splitText } from '@/lib/chunk';
export const runtime = 'nodejs';
export async function POST(request: Request) {
// Add authentication here before this route goes anywhere near production.
const { source, text } = await request.json();
const pieces = splitText(text);
const { embeddings } = await embedMany({
model: 'openai/text-embedding-3-small',
values: pieces,
});
await connectDB();
await Chunk.insertMany(
pieces.map((piece, i) => ({ text: piece, source, embedding: embeddings[i] }))
);
return Response.json({ stored: pieces.length });
}
Retrieve the closest chunks with a vector search
To search, embed the question with the same model, then run a $vectorSearch aggregation. The $vectorSearch stage reference says the stage must come first in the pipeline. It also recommends a numCandidates value at least 20 times the number of results you want, and its scores fall between 0 and 1.// lib/retrieve.tsCall
import { embed } from 'ai';
import { connectDB } from '@/lib/mongodb';
import { Chunk } from '@/models/Chunk';
export async function retrieve(question: string, limit = 5) {
const { embedding } = await embed({
model: 'openai/text-embedding-3-small',
value: question,
});
await connectDB();
return Chunk.aggregate([
{
$vectorSearch: {
index: 'vector_index',
path: 'embedding',
queryVector: embedding,
numCandidates: limit * 20,
limit,
},
},
{ $project: { _id: 0, text: 1, source: 1, score: { $meta: 'vectorSearchScore' } } },
]);
}retrieve('your question') from a test script and read the passages it returns. They should be relevant to the question even when the wording differs from your documents. Using one embedding model for documents and another for questions is the classic mistake, since their vectors do not share a map.
Generate and stream the answer in a chat route
Now give the retrieved passages to a language model as context and stream its reply. The pattern below follows Vercel's guide to a RAG chat app, without its citation and reranking extras. The system prompt tells the model to answer only from the context, which keeps it from inventing facts.// app/api/chat/route.tsTreat the model name here as an example, and swap in any chat model your gateway offers. Next.js's own streaming example uses older AI SDK function names, which is why checking your installed version matters. If the build complains about an import, look up its current name in the AI SDK docs.
import {
convertToModelMessages,
createUIMessageStream,
createUIMessageStreamResponse,
streamText,
toUIMessageStream,
type UIMessage,
} from 'ai';
import { gateway } from '@ai-sdk/gateway';
import { retrieve } from '@/lib/retrieve';
export const runtime = 'nodejs';
export async function POST(request: Request) {
const { messages }: { messages: UIMessage[] } = await request.json();
const question = messages
.at(-1)!
.parts.filter((part) => part.type === 'text')
.map((part) => part.text)
.join(' ');
const chunks = await retrieve(question);
const context = chunks.map((c, i) => `[${i + 1}] (${c.source}) ${c.text}`).join('\n\n');
const stream = createUIMessageStream({
execute: ({ writer }) => {
const result = streamText({
model: gateway('openai/gpt-5-mini'),
system:
'Answer using only the context below. If the answer is not in the context, say you do not know.\n\n' +
context,
messages: convertToModelMessages(messages),
});
writer.merge(toUIMessageStream({ stream: result.stream }));
},
});
return createUIMessageStreamResponse({ stream });
}
Build the chat page
The useChat hook from @ai-sdk/react sends messages to your route and renders the streamed reply as it arrives.// app/page.tsxType a question and the answer should appear word by word. If nothing streams, open the browser's network tab and read the response from
'use client';
import { useState } from 'react';
import { useChat } from '@ai-sdk/react';
import { DefaultChatTransport } from 'ai';
export default function Page() {
const [input, setInput] = useState('');
const { messages, sendMessage, status } = useChat({
transport: new DefaultChatTransport({ api: '/api/chat' }),
});
return (
<main>
{messages.map((m) => (
<div key={m.id}>
{m.parts.map((p, i) => (p.type === 'text' ? <p key={i}>{p.text}</p> : null))}
</div>
))}
<form
onSubmit={(e) => {
e.preventDefault();
sendMessage({ text: input });
setInput('');
}}
>
<input value={input} onChange={(e) => setInput(e.target.value)} />
<button disabled={status !== 'ready'}>Ask</button>
</form>
</main>
);
}/api/chat, because most failures show up there as an error message.
How to check that the whole system works#
Test with three kinds of question. Ask something your documents answer directly, and the reply should match them. Rephrase it in different words, and retrieval should still find the right chunk. Then try something your documents never mention, and the model should say it does not know. If that last test fails, tighten the system prompt and lower the number of retrieved chunks.
Where to improve next#
Once the basics work, three upgrades give the biggest gains. Add a filter so users only search the documents they may see. Add reranking, which reorders the retrieved chunks before the model reads them. Stream the sources to the browser so users can check each answer. Vercel's guide covers the last two, and MongoDB's $vectorSearch stage supports pre-filtering through its filter option.
Treat documents as untrusted input as well. A passage can contain instructions aimed at the model. Keep your system prompt firm, and never give the model tools it should not use on a user's behalf.
Common questions#
Do I still need Express?
No, not for this particular build. Next.js Route Handlers cover the API work. Keep Express if you already have an API, or if ingestion jobs run long and belong in a separate service.
Why store vectors in MongoDB instead of a separate vector database?
Keeping vectors next to your documents means one database to run and back up. Vercel's guide lists dedicated stores such as Pinecone and Upstash Vector as alternatives, so the choice depends on your scale and your team.
Do I need LangChain?
No. The steps above call the embedding model, MongoDB and the chat model directly, which makes each stage easy to see and debug. MongoDB also documents a LangChain.js integration if you prefer a framework.
Next steps#
You now have the full loop in one project: documents become chunks, chunks become vectors, vectors answer questions, and Next.js streams the result. Add your own documents, test the three question types, then add filters and sources. To go deeper into building with language models, see the generative AI course syllabus and certification post, or explore Expertzlab's Artificial Intelligence training in Kochi.
Build Scalable Web Applications with Modern Tech Stacks
Master full stack architecture, Next.js, React, Node.js, and GenAI integration for enterprise-grade scalability.
Expertzlab Team
Senior Technical Architect with 25+ years of industry experience across enterprise architecture, AI, Big Data, and Full Stack development. Mentor and founder at Expertzlab.
Want the full curriculum & fee structure for Java Full Stack & Microservices?
Includes module-by-module breakdown, project capstones & placement roadmap.
Related Tech & Career Guides
 Data Science
ROS 2 and Computer Vision Career Roadmap for Robotics Engineers
Follow a clear ROS 2 and computer vision career roadmap for robotics engineers. Skills, tools, projects and a 12-month study plan from Expertzlab in Kochi.
 Data Science
What Is MLOps and Why It Matters for Data Science Jobs
What is MLOps? See how the lifecycle works and why deployment skills now matter for data science jobs in India. A plain-language guide from Expertzlab.
 Data Science
How Generative AI Is Used in Data Analytics Workflows
See how generative AI in data analytics helps with cleaning, SQL, code and reporting, and where a human must still check the output. A practical guide.
Have Any Questions? Talk to an Advisor
Our expert career advisors are available 6 days a week to help you choose the perfect certification program and guide your tech career journey.